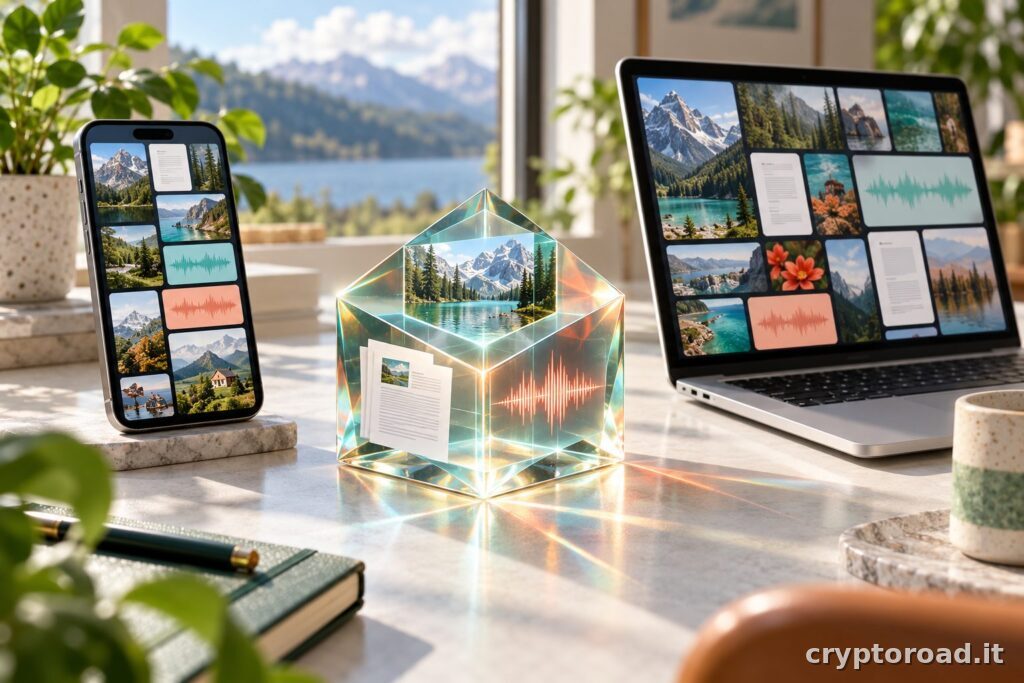
EmbeddingGemma 2 is Google’s model for finding content by meaning, including cases where a written question should retrieve a photograph, recording or document. Announced on October 6, 2026, it is particularly relevant to developers exploring local search without automatically sending an entire collection to a remote service.
The interesting question is not whether a computer can run yet another chatbot. It is whether an application can find the right evidence before an assistant interprets it: a moment in a video, an unlabelled photograph or a note written using different words from the search query.
EmbeddingGemma 2 and the role of local retrieval
The official model card describes a modular multimodal model with 740 million parameters and a shared 768-dimensional representation. Text, vision and audio encoders produce vectors rather than conversational answers.
A search application can compare the query vector with representations of indexed material. Similarity suggests a possible semantic relationship; it does not establish that a document is accurate, current or an exact match for the user’s intention.
This matters in financial archives. Finding something that resembles a payment receipt does not prove a payment happened, and retrieving an Ethereum document does not certify that its instructions remain valid. Search quality and factual verification are separate responsibilities.
Specifications that need context
| Component | Published specification | Practical implication |
|---|---|---|
| Purpose | Multimodal embeddings | Retrieval, not a standalone chatbot |
| Architecture | 740 million parameters overall | Not the application’s total memory usage |
| Output | 768 dimensions, with smaller options | Measure storage and retrieval quality together |
| Deployment focus | Consumer devices | Check compatibility on the actual target hardware |
Parameter counts cannot tell you whether an application will feel responsive on an inexpensive phone. The application process, database, loaded files and other system components also consume resources. A model specification is not a complete device requirement.
For a useful evaluation, separate idle memory, peak indexing memory and query latency. A fast demonstration with a small collection may say little about a library that includes long videos or changes throughout the day.
Why an embedding model is not a complete RAG system
EmbeddingGemma 2 can supply one part of a retrieval-augmented generation pipeline. Document splitting, permissions, ranking and source presentation still need deliberate implementation. A language model cannot repair evidence that retrieval never found.
Our coverage of NeoMME and Visual RAG offers useful context for visual document retrieval. The right comparison starts with the errors in your collection, rather than with whichever model has the newest name.
An invoice archive and a personal photo collection have different priorities. Exact references can matter more than conceptual similarity in the former, while natural-language descriptions may help locate pictures that have never been labelled in the latter.
A practical example: locating a moment in a recording
Imagine a collection of technical lessons and the query “the section where a security key is demonstrated.” This is an illustrative scenario, not a benchmark we have run against the model.
A useful application would return relevant segments with references to the original recordings. Its value comes from allowing the user to open the evidence and check the context, not from having an assistant invent a plausible explanation.
Testing therefore needs questions with known answers as well as questions the collection cannot answer. “No suitable result” must remain a valid outcome. Forcing a match every time may make a demo look helpful while making the finished product less dependable.
What the Android demonstrations establish
The Google AI Edge announcement presents media-search and video-retrieval demonstrations. These are vendor examples, not independent measurements of performance on professional archives, unusual languages or every class of phone.
The announcement also separates the demonstrations from planned Android service availability through ML Kit. An integration described as coming in subsequent weeks should not be treated as universally available without checking the current platform documentation.
For readers following on-device AI, the local Gemma 4 requirements in Android Studio provide a related but different example. Assisted development and generative inference are not the same workload as producing embeddings.
Local processing is not a complete privacy policy
Running inference on a device can reduce the need to transfer files, but the surrounding application determines where information actually travels. Cloud backup, telemetry, sync and diagnostic logs can still expose data beyond the local machine.
The index itself deserves protection. File names, paths and saved search results can reveal sensitive information even when the underlying documents remain encrypted elsewhere. Access controls should apply before retrieval results are displayed, not merely after a user opens a file.
When an evaluation makes sense
EmbeddingGemma 2 is worth considering when the task involves finding mixed media locally or supplying evidence to an assistant. It is a less obvious choice when ordinary structured search already finds exact codes reliably and cheaply.
Start with a small, representative, non-sensitive collection and write the questions before running the test. Compare useful results, missed answers, indexing time, resource consumption and maintenance effort against the existing search tool.
There is also an operational question: who rebuilds the index when files change, and how does the application handle deleted material? A promising model does not remove those responsibilities. The integration is worthwhile only if the complete search experience improves enough to justify its additional moving parts.