OpenAI’s Decisions API entered public beta on October 6, 2026, using GPT-6 Luna to return typed judgments instead of lengthy conversational responses. It targets applications that classify requests, choose among categories or prioritize many items without turning every small operation into a chat.
This is a concrete development beyond the DevDay announcement: a dedicated endpoint and operational documentation are now available. It does not mean the model should make every business decision independently. Its output is an assessment within a system that still needs rules, thresholds and controls.
Decisions API: what an application receives
The official changelog records the beta release. The documentation distinguishes three question types for tasks with a small, bounded result rather than an open-ended response.
| Type | Suitable question | Result |
|---|---|---|
| Predicate | Is a condition present? | Estimated probability |
| Choice | Which predefined category fits? | A selection from supplied options |
| Score | Which ordered level describes the case? | A score based on the level distribution |
| Service status | Is general availability complete? | Public beta, not a completed GA release |
A choice among departments is not free-form prose. An urgency score is not permission to act. A restricted format makes integration easier, but does not prove that the interpretation of the input is correct.
Example: routing support messages
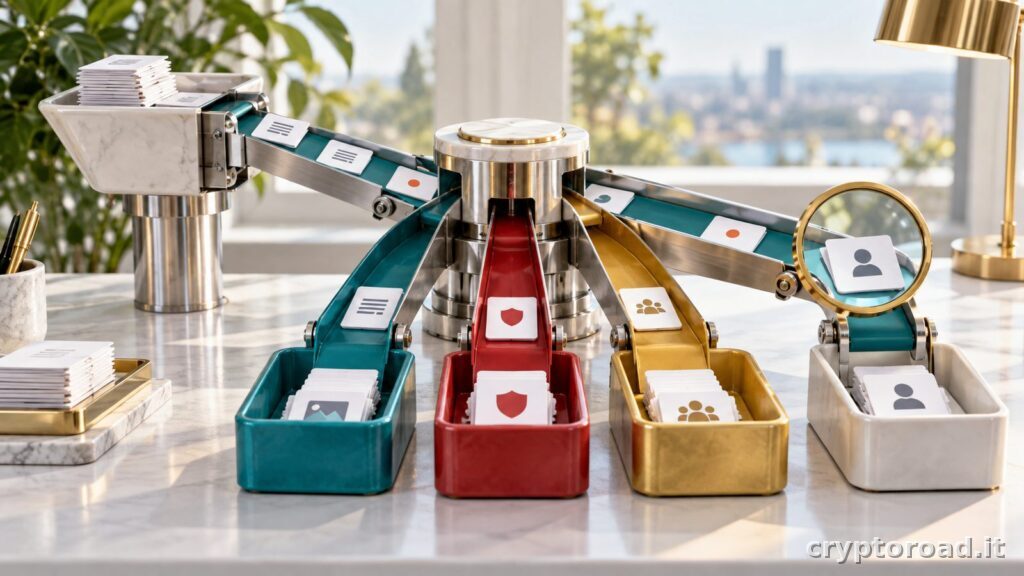
Imagine three destinations: billing, technical support and human review. The application receives a message and chooses the most plausible path. This is different from composing a complete answer to the customer; the assignment is a small intermediate judgment.
Categories need distinct meanings. If “account problem” and “technical problem” overlap without criteria, ambiguity already exists in the process. A review path prevents every unclear message from being forced into an unsuitable department.
The official Decisions API guide documents the GPT-6 Luna workflow. Possible use cases are not measured accuracy for your service. You need labeled examples and expected results before deciding whether routing is reliable enough.
Pricing and the difference from Responses
The documented base price for this endpoint is $0.10 per million input tokens, with no output-token or cache-operation charges. Regional processing premiums and applicable long-context multipliers still matter. It is not an unconditional universal rate for every request.
For a simple arithmetic illustration, 10,000 requests containing 1,000 input tokens each total ten million tokens and cost $1 at the base rate. This is not a production estimate. Images, extra evidence, retries and applicable processing terms can change the total.
Requests to the same model through other endpoints follow their relevant pricing. Seeing gpt-6-luna in two services does not let you transfer cost assumptions and behavior from one to the other.
How to interpret the speed claim
OpenAI describes these judgments as substantially faster than conversational use through Responses. That is the provider’s comparison, not a guaranteed improvement for every network, input or application. Treat “up to ten times faster” as a claim to evaluate for the relevant task.
Measure the whole path: preparing evidence, sending the request, validating the answer and handling failures. A fast call does not improve an unclear process if many results require manual correction. Missing context can also make a quick answer less useful than a slower, well-defined one.
Compare the same question on a fixed sample. Do not contrast a short classification with a long report and conclude that one product is universally superior. The output being requested is part of the performance comparison.
Supported evidence and refusals
The endpoint reference describes text and inline images. This is not an agent that independently browses websites, opens arbitrary files or operates tools. Evidence must be supplied through the supported request format.
A question can also return a refusal. Application code must distinguish a valid judgment from a question that was not evaluated. An absent answer is not evidence that a condition is false. Timeouts and service failures likewise require an explicit path.
A conservative fallback can send the case for human review. It must not silently turn a technical failure into approval. This matters especially when classification influences accounts, payments or public content, where an unnoticed error can have consequences beyond a wrong label.
Probability is not proof
A high number expresses a model estimate, not verified certainty. Set thresholds according to the consequences of mistakes. Misrouting a generic question and overlooking an urgent request are not equivalent errors, so they should not automatically share the same decision rule.
The distinction between semantic judgment and a hard rule is also central to our explanation of TypeSafe AI’s Jev. Similar problem types do not imply equivalent APIs, prices or quality. Each product still needs its own evaluation.
Use deterministic code for arithmetic, reliable parsing and authorization. A model is useful when meaning must be interpreted under ambiguity, not when an exact rule already resolves the assignment more reliably and transparently.
When a different API fits better
If you need a complex object, an extended explanation or tool calls, choose the product designed for that result. Decisions is not a universal replacement for structured generation or agent workflows. A narrow result can be valuable precisely because it does not attempt everything.
Our DevDay report provides the broader platform context. This beta adds a more specialized component: an identifiable, testable judgment inside a larger application process.
Before adopting it, test ordinary, ambiguous and adversarial examples, define fallbacks and inspect whether the choices actually improve the workflow. The useful change is not handing everything to AI. It is giving the model a narrower question while retaining control over the consequences.